SEO Incrementality Testing: Measure the Traffic Your Changes Actually Create
Rankings and traffic shifts don’t prove that an SEO change caused the result. Learn how to design controlled tests, choose comparable page groups, and estimate the organic gains your work truly generated.
An increase in organic traffic after an SEO change is not necessarily traffic created by that change. Demand may have risen, a competitor may have lost visibility, or a search update may have helped the entire site. SEO incrementality testing addresses a more useful question: how much traffic did the changed pages receive compared with what they would probably have received without the change?
The practical approach is to change one group of pages while leaving a comparable group unchanged, then compare their performance against a documented baseline. This walkthrough explains how to design that comparison, estimate incremental organic gains, and decide whether the evidence supports rolling out the change.
What SEO Incrementality Testing Can—and Cannot—Prove
Incrementality is the difference between an observed outcome and a counterfactual: the outcome you would expect without the intervention. You can observe traffic after editing a page, but you cannot simultaneously observe that same page, under identical conditions, without the edit. A control group helps estimate that missing outcome.
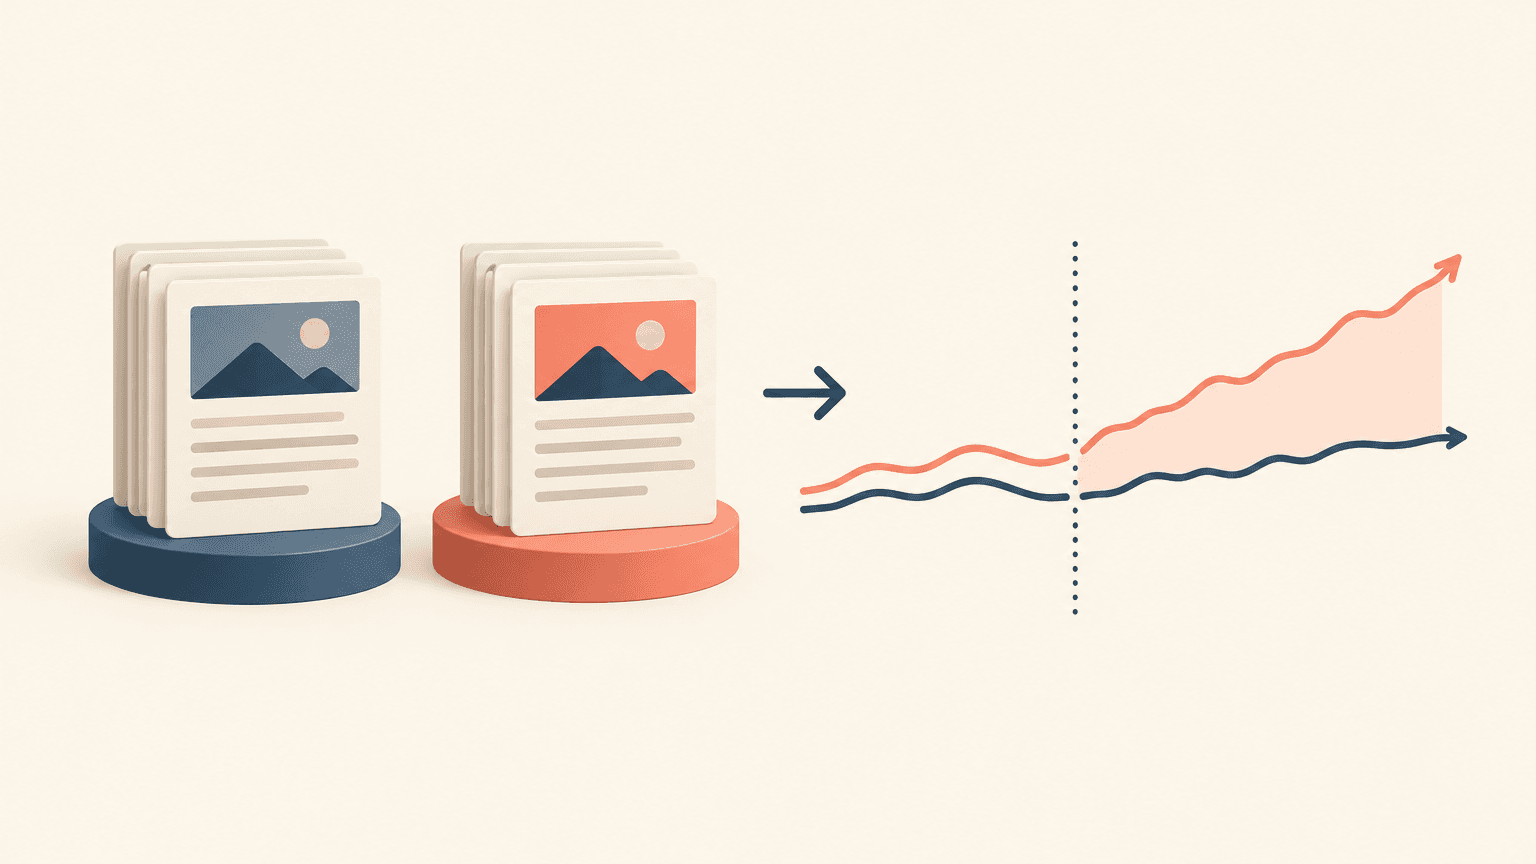
In a page-group test, treatment pages receive a defined SEO change and control pages do not. Both groups remain exposed to the wider search environment. If they tracked each other reliably before the intervention, a subsequent divergence can provide evidence of the change's effect. Random assignment within comparable groups strengthens that evidence by reducing systematic differences between treatment and control.
This is different from a conventional user-level A/B test. The experimental unit is usually a URL or a cluster of related URLs, not an individual visitor. The goal is to measure how search performance changes when a stable set of pages receives an intervention, rather than showing alternate SEO versions to different users or crawlers.
A well-designed test can estimate the effect of a specific change on the tested pages, during the observed period, subject to its assumptions.
It cannot establish that every similar page will respond equally or that an observed gain will persist indefinitely.
It cannot automatically distinguish newly created site traffic from clicks shifted away from other pages on the same site.
It cannot isolate individual causes when several changes are introduced together; in that case, it estimates the effect of the combined package.
Treat incrementality as an estimate with uncertainty, not a precise count of clicks that unquestionably came from your work. The credibility of the estimate depends on the comparison group, implementation quality, and absence of important unaccounted-for differences.
Choose a Change and Define the Outcome Before Testing
Start with a change that can be applied consistently to a subset of pages without altering the control group. Examples include revising title templates, adding a useful content module to category pages, or improving a specific on-page navigation element. Broad migrations and sitewide architecture changes are harder to evaluate with this method because a credible untouched comparison may not exist.
Write the hypothesis as a mechanism, intervention, and expected outcome. A hypothetical example is: adding clearer product-type language to category titles will make those results more relevant to applicable searches and increase organic clicks. This is more testable than a goal such as improving SEO because it specifies what changes and which outcome should respond.
Primary outcome: choose one main measure, such as Google Search Console clicks to eligible pages.
Secondary measures: use impressions, click-through rate, and position trends to help interpret the result, not to replace an unsuccessful primary outcome after the fact.
Business guardrails: monitor relevant conversions, revenue, engagement, or lead quality where measurement is reliable.
Population: record eligible URLs, exclusions, search type, and any country or device restrictions before assignment.
Decision threshold: define the smallest gain worth implementing, considering development effort, maintenance, and potential harm.
Timing and stopping rules: document the baseline, deployment, expected crawl or indexing delay, evaluation window, and conditions that would invalidate or stop the test.
Choose metrics with their measurement boundaries in mind. Search Console clicks represent clicks from the selected Google search surface, not all organic search traffic. Analytics sessions use different collection and attribution rules and may be affected by consent or tracking changes. Use one consistent source for the primary analysis rather than treating these measures as interchangeable.
Do not choose a universal test duration. The necessary observation period depends on traffic volume, variability, the effect size you need to detect, and how quickly search engines process the change. Use historical data to assess whether a commercially meaningful effect could be distinguished from ordinary noise. If not, expand the eligible population, test a stronger intervention, or accept that the available data cannot answer the question reliably.
Build Comparable Treatment and Control Page Groups
Begin with pages that share a template, purpose, and search behavior. Comparing product pages with editorial articles is usually weak because their demand patterns, ranking opportunities, and conversion paths differ. Even within one template, separate pages whose performance is driven by a different region, buying season, or branded query mix.
Match on behavior, then randomize where possible
Use the pre-test period to compare traffic levels, weekly patterns, trends, and volatility. Similar totals alone are insufficient: a steadily growing page and a declining page may have the same average traffic but make poor counterparts. Form comparable strata or matched sets, then randomly assign pages within them to treatment or control. Preserve the assignment rather than moving disappointing pages between groups after launch.
Compare baseline organic clicks and impressions, including whether a few URLs dominate each group.
Check trend direction and responses to known demand peaks across a sufficiently representative baseline.
Inspect device, country, query intent, and branded versus non-branded exposure where data permits.
Exclude or separately handle pages with planned redirects, major inventory instability, indexability problems, or concurrent campaigns.
Confirm that both groups have comparable measurement coverage and use stable URL identifiers.
Many URLs do not necessarily provide much independent evidence. Related pages can move together, and a handful of high-traffic pages can dominate the result. Account for these relationships in both assignment and analysis. Where pages compete for substantially the same queries or share a tightly connected topic, assigning the whole cluster together may reduce interference, although it leaves fewer independent units.
Check for spillover before deployment
A control group must remain meaningfully untreated. A shared template edit can accidentally change both groups. Internal linking changes may affect destination pages even when their own HTML is untouched. Query overlap can also shift clicks from control pages to treatment pages, exaggerating the apparent benefit. Map these dependencies before launch, verify rendered output, and monitor relevant pages outside the experiment.
Before making the change, run a historical placebo check: choose a pretend intervention date within the baseline and apply the proposed analysis. Repeated apparent effects when nothing changed suggest that the groups or model are unreliable. This check does not prove validity, but it can expose a weak design before engineering time is spent.
Account for Seasonality, Site Changes, and Search Demand
A concurrent control is valuable because it experiences the same calendar as the treatment. If demand lifts both groups similarly, the control can help separate that shared movement from the treatment effect. Comparing only with the previous month or the same period last year cannot reliably do this: holidays move, product availability changes, and search results evolve.
However, shared timing does not guarantee shared exposure. A search update might affect one topic or page type more strongly than another. A seasonal peak might apply only to products concentrated in treatment. Inspect whether the groups remained comparable rather than assuming that the control removed every external influence.
Maintain an event log covering releases, outages, robots directives, canonical changes, redirects, promotions, inventory changes, and measurement updates.
Verify treatment delivery on a sample of URLs and record when changes became accessible to crawlers.
Use available crawl or inspection evidence to assess uptake, while recognizing that crawl detection is not proof of a ranking response.
Monitor demand indicators and query composition as context. A rise in impressions alone does not prove rising demand because visibility can also change.
Check whether external events affected treatment and control differently; document any reason the original comparison may no longer be credible.
Allow for delayed uptake without selecting the most favorable start date afterward. Define a practical transition window before launch and report how it is handled. If a major disruption undermines the comparison, use the predefined invalidation rules or report the test as inconclusive. Removing unfavorable days simply because they lower the result produces a biased estimate.
Analyze Results and Estimate Incremental Organic Gains
Start by graphing daily or weekly treatment and control performance across the baseline and test period. Look for implementation timing, pre-existing divergence, missing data, and isolated spikes. Then apply the estimator chosen before launch. The key output is not simply treatment growth; it is observed treatment performance minus an estimate of treatment performance without the change.
A transparent proportional-control example
In this hypothetical example, treatment pages received 20,000 clicks during the baseline and control pages received 25,000. In an equally long evaluation period, control clicks rose to 27,500, a 10% increase. If the treatment would have followed the same proportional movement without the change, its expected clicks would be 20,000 × 1.10 = 22,000.
Suppose treatment actually received 24,200 clicks. The estimated incremental gain is 24,200 − 22,000 = 2,200 clicks. Relative lift is 2,200 ÷ 22,000 = 10%. The treatment's raw growth was 21%, but attributing that entire increase to the edit would ignore the growth reflected in the control.
This calculation is an illustration, not a complete statistical test. It assumes the groups would have maintained a stable proportional relationship without treatment. A difference-in-differences model instead typically relies on comparable untreated trends on its chosen scale. Choose and validate the assumption that fits the data; do not switch models to obtain a preferred answer.
Quantify uncertainty and test the interpretation
For a decision-grade analysis, use an approach suited to the assignment and data: a randomized page-group estimator, a difference-in-differences model, or a validated counterfactual time-series model may be appropriate. Non-randomized comparisons require stronger assumptions about unmeasured differences. More complex modeling does not repair a contaminated control or an intervention that was implemented inconsistently.
Report an uncertainty interval with the point estimate, using methods that account for repeated observations and correlated pages. Daily observations are not independent replications of the experiment. Resampling or standard errors should respect the assignment unit and relevant time dependence. If the team lacks this expertise, obtain statistical review rather than applying a generic significance calculator to daily click totals.
Check whether the conclusion depends on one unusually large page, an arbitrary baseline, or a single spike. Use planned sensitivity checks and report disagreements rather than choosing the most positive variant. Review neighboring pages and query clusters for losses that could indicate cannibalization. A gain within treatment is not necessarily a net gain for the site.
Positive and decision-relevant: the estimated benefit and uncertainty support the implementation cost, with acceptable guardrails. Consider a staged rollout and continued monitoring.
Negative: the evidence supports harm or an unacceptable tradeoff. Revert where practical and investigate the mechanism.
Inconclusive: the plausible range includes materially different business decisions. Do not translate this into proof of no effect.
Small but well-estimated: the effect may be real yet too small to justify maintenance or expansion.
Translate clicks into business value cautiously. Extra clicks may come from different intents and convert differently from existing traffic. Measured conversion outcomes are preferable where volume and tracking support them. Otherwise, label any value calculation as a scenario based on assumptions, not demonstrated incremental revenue.
Common Testing Mistakes and How to Avoid Them
Selecting only recent losers for treatment: a rebound can reflect regression to the mean. Define eligibility before inspecting short-term declines and randomize among comparable pages.
Changing several elements but crediting one: test a single intervention or clearly label the result as the effect of a bundle.
Using average ranking as the sole success metric: changing query composition can distort the average. Keep clicks or another chosen outcome primary and use ranking data diagnostically.
Stopping when a dashboard first looks positive: repeated checking and opportunistic stopping increase false-positive risk. Use the planned window or a statistical method designed for sequential monitoring.
Searching many subgroups for a winning story: exploratory findings need explicit labeling and, where important, a follow-up test.
Treating a tracking failure as a traffic effect: validate data completeness and collection changes before interpreting a divergence.
Assuming more days always fix weak evidence: additional time may help, but it also creates more exposure to changing conditions. Reassess feasibility instead of extending indefinitely.
Keep a concise test record containing the hypothesis, URL assignments, implementation checks, event log, metric definitions, analysis method, uncertainty, and decision. Include failed and inconclusive tests. Without that record, teams can repeatedly pursue ideas that appeared promising only because the wider market was growing.
For your next test, choose one repeatable page template and one isolated change. Before deployment, build the eligible URL list, verify that candidate groups track each other historically, and write down the outcome and decision rules. If you cannot construct a credible untreated comparison, resolve that design problem first rather than launching a test whose result will remain ambiguous.