SEO for JavaScript Websites: Diagnose Rendering Gaps and Get Key Pages Indexed
JavaScript can leave important content invisible or incomplete to search engines. Learn how to test rendered pages, spot indexing blockers, and prioritize fixes that help search engines find your key content.
If a JavaScript-heavy page is missing from search, first check whether the search engine can discover its URL, retrieve the page, render its main content, and recognize it as an indexable, distinct page. These are separate problems. Moving the entire site to server-side rendering will not fix a blocked URL, an incorrect canonical tag, or a page that offers little unique value.
Start with a small set of important URLs: a high-value category page, a product or service page, and a recently published page from each affected template. Compare them with an indexed page that uses the same technology. The walkthrough below helps you isolate the failure, choose a proportionate fix, and verify that search engines receive the content you intend.
How Search Engines Process JavaScript Pages
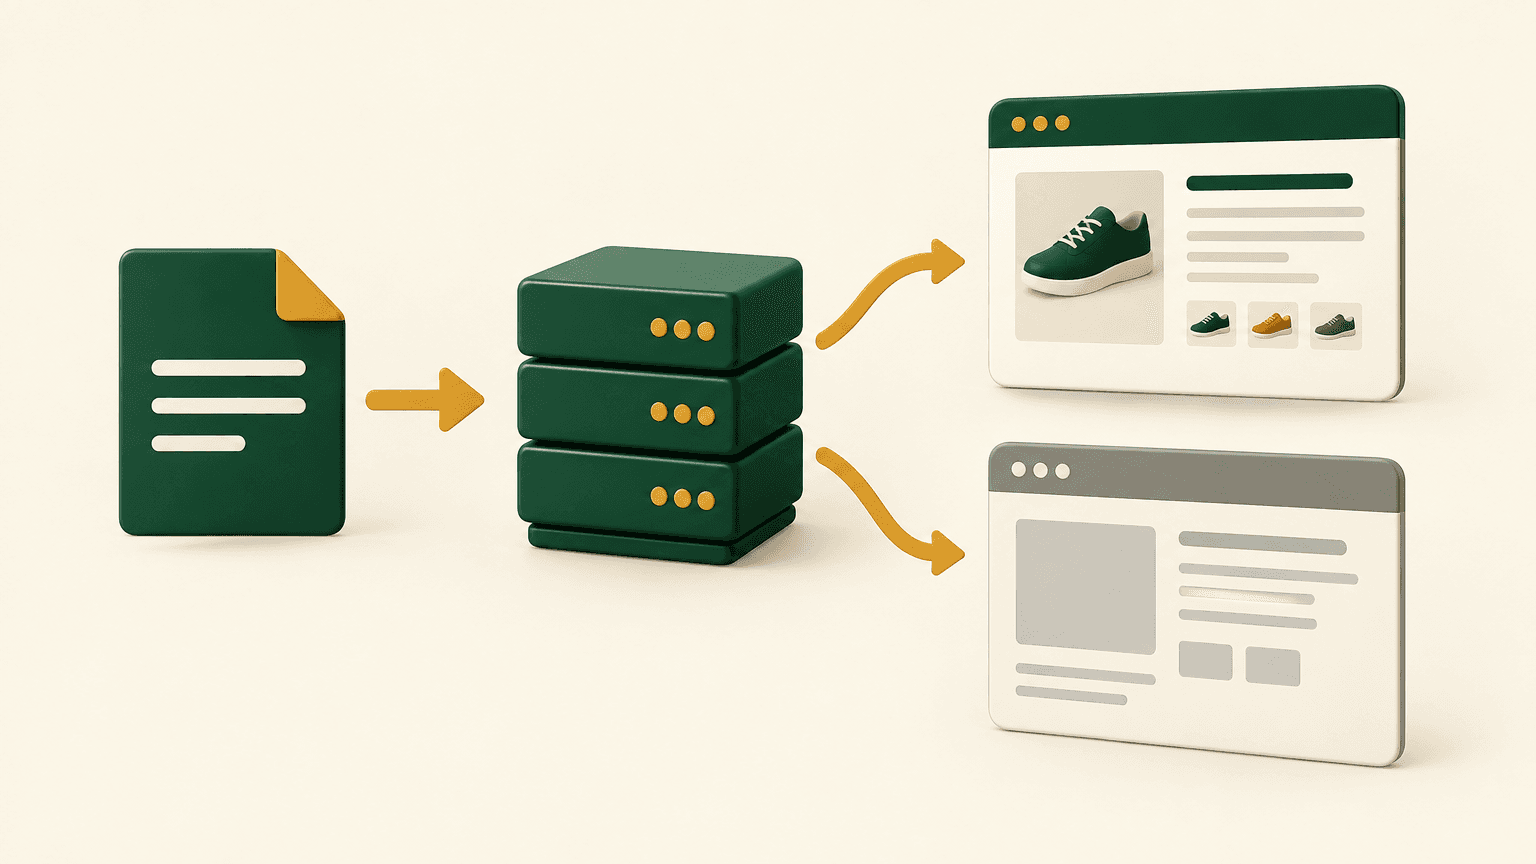
Search engines first need to discover a URL, usually through links or a sitemap. When they request it, the server returns an HTTP response containing headers and HTML. On a client-rendered site, that HTML may contain little more than an application shell and references to JavaScript files. The page becomes useful only after scripts execute and fetch the data needed to build its content.
Google can render JavaScript using a browser-based rendering system, but fetching, rendering, and indexing are not the same event. Rendering may happen separately from the initial crawl, and successful rendering does not guarantee indexing. Other search engines and crawlers have different capabilities, so do not assume that every automated visitor can run your application like a user's browser.
Separate the Four Stages Before Troubleshooting
Discovery: Can a crawler find the URL through accessible links or a sitemap?
Fetching: Does the URL return the intended response without robots.txt restrictions, authentication, server errors, or challenge pages?
Rendering: Can the rendering system load the required resources and produce the main content, links, and metadata?
Indexing: Is the resulting page eligible for indexing, and does the search engine select it rather than a duplicate or another canonical URL?
A page can pass one stage and fail the next. For example, a sitemap can make a product URL discoverable while its product API fails during rendering. Conversely, a page can render perfectly but remain excluded because it contains a noindex directive or points its canonical tag to another URL. Record the evidence for each stage rather than treating every exclusion as a JavaScript problem.
A page working in your browser proves only that it works in that session. Your browser may have cookies, cached data, stored credentials, or a service worker that a fresh crawler session does not have.
Symptoms of Rendering and Indexing Problems
Look for patterns across templates, not just individual URLs. If every page using a new application component disappears from search while older pages remain indexed, a shared rendering or routing issue deserves attention. If only near-identical filter URLs are excluded, duplication and canonicalization may be the more likely explanation.
The fetched HTML contains an empty application container, and the rendered output also lacks the page's main text. Investigate script execution, data fetching, and resource access.
The rendered page shows a loader, error message, or consent overlay instead of useful content. Test dependencies on cookies, user interaction, and third-party services.
Pages are indexed, but many share the same title or description. Check whether route-specific metadata is delivered correctly and whether navigation leaves stale metadata behind.
Deep URLs work after clicking through the application but fail when opened directly. Check server routing and fallback behavior.
Important URLs have few or no internal links. Check whether navigation uses actual anchor elements with usable href attributes rather than click handlers alone.
Search Console reports crawled pages that are not indexed. Inspect rendering, but also evaluate duplication, thin content, canonical signals, and the usefulness of the page.
Invalid routes return a successful response and a generic app shell. Check for soft 404 behavior and missing server-side status handling.
Search result snippets and site: searches can provide clues, but they are not reliable inventories of indexed pages or definitive rendering tests. A missing snippet does not prove that Google cannot read your content. Use URL-level inspection and direct technical tests to establish what is actually happening.
Test Pages with Crawlers and Search Console
Step 1: Build a Representative URL Sample
Create a diagnostic sheet with each URL's template, business importance, HTTP status, indexability, declared canonical, internal link sources, and sitemap presence. Include both affected and healthy pages. Add a nonexistent URL to test error handling and a direct deep link to test routing. This sample gives developers reproducible cases and prevents an isolated failure from driving a sitewide architecture change.
Step 2: Compare Response HTML with Rendered HTML
Use a crawler that supports both HTML-only and JavaScript-rendered crawling. Run the same URL sample in each mode and keep the crawl settings comparable. Save the server response HTML and rendered HTML where the tool allows it. A rendered crawl shows what that tool's browser produced; it is useful evidence, but not an exact reproduction of Google's processing.
Compare the main heading, primary text, product or service details, and route-specific title.
Check robots directives in both HTML and HTTP headers, plus the canonical tag before and after rendering.
Compare internal links: are important destination URLs present as anchor links in the response, the rendered document, or neither?
Inspect structured data for missing fields, incorrect values, or information that does not match visible content.
Review failed scripts, stylesheet requests, API calls, redirects, and resource restrictions.
Check whether the renderer sees meaningful content without clicking, scrolling, signing in, or accepting a prompt.
Also open affected URLs in a fresh browser session and inspect the console and network panel. Look for uncaught errors, failed chunks, blocked cross-origin requests, API authorization failures, and content that appears only after user interaction. Disabling JavaScript is a useful way to inspect the fallback experience, but an empty page with JavaScript disabled does not by itself prove that Google cannot index it.
Step 3: Inspect Google's View of the URL
In Google Search Console, inspect the exact URL, including the correct protocol, hostname, path, and relevant parameters. Review its indexing status, crawl information, and canonical details where available. Distinguish the indexed information from a live test: the indexed view reflects Google's recorded processing, while the live test checks the current page and does not establish that it will be indexed.
Run a live test and inspect the tested page's HTML, screenshot, and resource information where available. Search the HTML for a distinctive sentence from the main content, not just the brand name or navigation. A screenshot can reveal a blank shell or an error screen, but it cannot confirm every link, directive, or item of structured data. Pair the visual check with HTML inspection.
Do not put noindex in the initial HTML and rely on JavaScript to remove it. Google may skip rendering after encountering that directive. Deliver the intended indexability state in the original response.
Step 4: Identify the Smallest Proven Failure
A hypothetical example: a category page loads correctly for returning users, but a fresh session and Google's live test show an empty grid. The network panel reveals that its inventory request requires a cookie created elsewhere in the application. The immediate fix is to make public category data available without that session dependency. Server rendering may still improve reliability, but it is not a substitute for understanding the failed request.
Choose Between Server-Side Rendering and Other Fixes
Prioritize fixes by the number and importance of affected pages, the strength of the evidence, and the engineering effort required. Repair incorrect status codes, blocked resources, broken links, and unintended indexing directives before undertaking a rendering migration. These failures can undermine any architecture.
Use Server-Side Rendering When Public Content Must Be Built per Request
Server-side rendering produces page HTML on the server rather than making the browser construct all essential content. It is a strong option when important pages need frequently changing public data and client rendering repeatedly fails to expose that data reliably. Deliver the main content, essential links, title, canonical, and indexing directives in the response; keep interactive features in JavaScript.
The tradeoffs include server workload, caching complexity, backend dependencies, and potentially slower responses when data sources are slow. Hydration, which connects client-side behavior to server-rendered markup, can also fail or replace correct HTML with incomplete content. Test both the original response and the hydrated page. SSR improves content availability; it does not guarantee discovery, indexing, or rankings.
Use Static Generation for Content That Can Be Published Ahead of Time
Static generation creates HTML before a visitor requests the page. It can suit editorial content, documentation, service pages, and other URLs whose core content changes on a manageable publishing schedule. It reduces dependence on runtime data fetching for the initial content, but large URL inventories and frequent updates require a practical build or regeneration strategy. Confirm that updates and removed pages propagate correctly rather than leaving stale HTML available.
Keep Client Rendering Where Targeted Repairs Are Enough
Fix discovery with crawlable anchor links and sitemaps containing preferred, indexable URLs.
Remove accidental blocks on resources required to render public content, while preserving restrictions on private areas.
Make primary content load without clicks or scrolling. Lazy-load secondary content where appropriate, but do not hide the page's purpose behind an interaction.
Repair routing so valid deep URLs load directly and missing pages return appropriate error responses.
Ensure each indexable route has consistent metadata and canonical signals, preferably present in the server response.
Reduce unnecessary script dependencies and isolate optional widgets so their failures do not prevent main content from appearing.
A hybrid approach is often practical: render public, search-relevant pages as HTML while keeping account dashboards, configurators, and other interaction-heavy areas client-driven. Choose by page purpose rather than insisting on one rendering model for the whole site. Private or personalized pages generally do not need to become search landing pages.
Serving a separate rendered version only to crawlers adds maintenance and content-parity risks. Google treats dynamic rendering as a workaround rather than a recommended long-term solution. Prefer an architecture that gives users and crawlers equivalent core content.
Validate Changes and Monitor Important URLs
Validate the original URL sample after deployment using the same tests and crawl settings. Check more than the screenshot: a page can look correct while returning the wrong status, retaining a noindex header, or declaring another page as canonical. Include cold-cache requests and direct visits to deep URLs so cached content or prior navigation does not hide a regression.
Verify that primary content, headings, metadata, and essential links appear in the intended HTML output.
Check that hydration does not remove content or change canonical and robots signals incorrectly.
Repeat rendered crawling and Search Console live tests for each affected template.
Verify sitemap entries and internal links point to the intended canonical URLs.
Check that scripts and public data endpoints remain accessible and that the fix has not exposed private data.
For a small number of priority pages, use Search Console's request-indexing option after validation if it is available. Keep sitemaps current for broader URL discovery. Neither action forces indexing or supplies a dependable completion deadline. Search engines still need to revisit pages, process them, and decide whether to include them.
Monitor Technical Recovery Separately from Search Performance
Track whether the main content is consistently available, whether crawl and rendering errors decline, and whether important URLs become indexed under the intended canonical. Then monitor impressions and clicks for those pages. Search performance may also change because of demand, competition, content quality, and other factors, so an indexing repair should not be judged solely by an immediate traffic increase.
Add automated checks to releases for your key templates: response status, indexability, canonical URL, main-content presence, and internal links. Where server logs are available, use them to investigate repeat request failures and crawl patterns; verify crawler identities before drawing conclusions from user-agent strings. Logs show requests and responses, not proof that a page was rendered or indexed.
Your next step is to select one missing, high-value URL and one healthy comparison URL. Capture their response HTML, rendered content, and Search Console findings, then identify the first stage where they differ. Fix that demonstrated failure, validate it across the affected template, and expand the work only when the evidence supports a broader change.