SEO for Orphan Pages: Find Valuable URLs and Restore Their Internal Links
Orphan pages receive little or no internal link support, making them harder to discover and evaluate. Learn how to find them, assess their value, and reconnect the pages worth keeping.
An orphan page can be live, useful, and even receiving search traffic while remaining unreachable through your site's internal links. The fix is not to link every forgotten URL from the footer. First identify which URLs are genuinely disconnected, decide which deserve a place in the site, and then add links where readers would naturally need them.
This walkthrough separates discovery from decision-making. You will build a candidate list from crawls, sitemaps, and performance data; check whether each page should remain accessible; and verify that your linking changes work. A spreadsheet and a crawler are enough to start, although analytics, server logs, and Google Search Console can reveal URLs a crawl cannot find.
What Makes a Page Orphaned—and Why It Matters
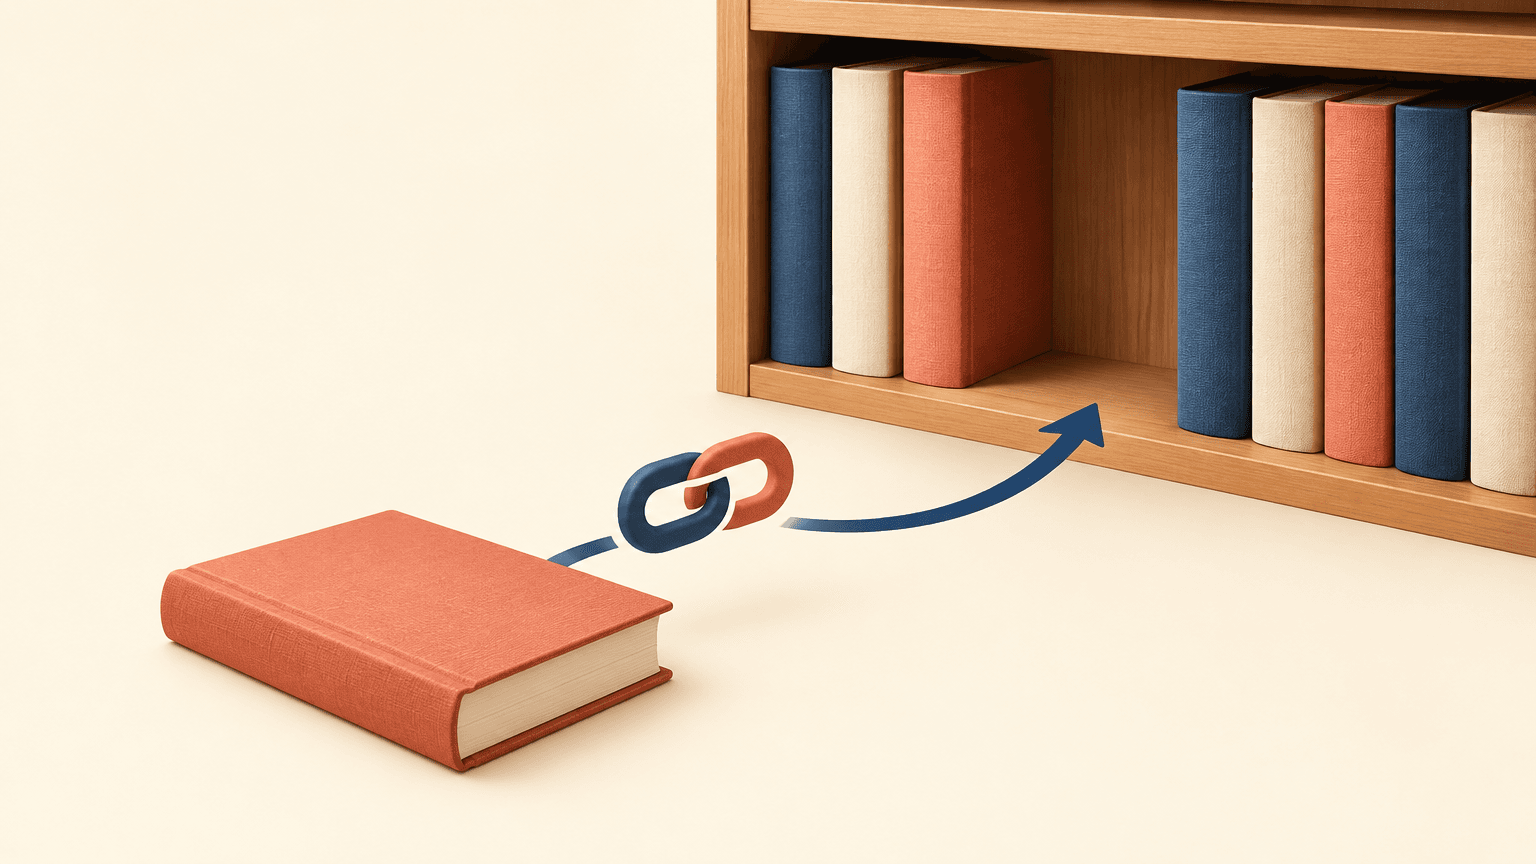
A strictly orphaned page has no incoming internal links from other pages on the site. That definition needs a practical qualification: a page may have links but still be effectively isolated if those links come only from other disconnected pages. A group of articles linking to one another does not become reachable simply because links exist within the group.
Weakly connected pages are a related but different problem. A guide linked only from a deeply buried archive is not technically orphaned, yet visitors and crawlers may struggle to reach it. Keep true orphans and weakly connected pages in separate categories so you can distinguish restoring access from improving an existing path.
True orphan: no incoming internal links are found within the audited site scope.
Disconnected cluster: pages link to each other but have no incoming path from the reachable site.
Weakly connected page: an internal path exists, but placement, depth, or relevance makes discovery difficult.
Intentionally isolated URL: a page is kept out of navigation for a specific purpose, such as a temporary campaign or account workflow.
Internal links help search engines discover URLs and understand relationships between pages. They also give visitors a route to information they would otherwise miss. A sitemap or external backlink may help a search engine discover an orphan URL, but neither provides a useful journey from your own related content. Being orphaned does not automatically mean a page is unindexed, and adding links does not guarantee indexing or higher rankings.
Define your audit boundary before counting links. If a help center lives on a subdomain, decide whether links from the main site count as part of the same content ecosystem. Record that choice so the report does not label deliberately connected pages as orphans.
Find Orphan URLs by Comparing Crawls, Sitemaps, and Analytics
A crawl that follows links from the homepage cannot discover every page with no incoming links. You need two datasets: the URLs reachable through the site's link structure and a broader inventory of URLs known from other sources. URLs in the broader inventory but missing from the reachable crawl are orphan candidates, not confirmed orphans.
Build a clean reachable-site crawl
Start a link-following crawl from the homepage and any other legitimate entry points in scope. For this baseline, avoid treating sitemap imports or manually supplied URLs as proof of internal discovery. If your tool combines discovery sources, preserve the source information so you can separate URLs found through links from those imported directly.
Review crawl restrictions before trusting the result. URL limits, excluded directories, robots rules, authentication, and rendering settings can all hide reachable pages. If navigation depends on JavaScript, compare the raw HTML with a rendered crawl. Otherwise, a crawler configuration problem may look like a site architecture problem.
Collect URLs the crawl may have missed
XML sitemaps: collect listed URLs, including those in child sitemaps. A sitemap entry shows intended discovery, not evidence of an internal link.
Analytics landing-page reports: look for URLs receiving visits across a period that reflects your site's publishing and seasonal cycles. Missing tracking or reporting limits can leave gaps.
Google Search Console: export available page-level performance and indexing information. These reports provide useful candidates but are not a complete inventory of every URL.
CMS or database exports: include published articles, products, resources, and other public content types that may have fallen out of navigation.
Server logs: where available, inspect requested URLs to find pages used by visitors or crawlers. Separate real content from malformed requests and parameter noise.
Historical migration files or backlink reports: use these to investigate older URLs that may still have value, while treating their current status as unverified.
Normalize the collected URLs before comparing them. Remove fragments, resolve relative paths, and account for known tracking parameters. Do not automatically lowercase paths or remove every query string: some systems treat letter case or parameters as meaningful. Keep the original URL alongside the normalized comparison key so you can investigate ambiguous matches.
Compare the combined inventory with the link-discovered URL set. Fetch unmatched candidates directly to check their response codes, redirects, canonical declarations, and robots directives. A URL that redirects to a reachable page is not the same problem as an isolated page returning a successful response. Likewise, a duplicate URL pointing to a preferred canonical version may need URL cleanup rather than new links.
For each candidate, record the URL, discovery source, response status, canonical target, indexability signals, incoming link count, traffic evidence, and proposed action. Confirm suspected orphans by checking incoming-link reports and the relevant templates or content records. A single source rarely proves that a URL has no internal links.
A zero-inlink result is only as reliable as the crawl coverage. Before changing the site, check whether the candidate was excluded by crawl settings, hidden behind a login, or linked through a rendering pattern your crawler did not process.
Check Which Pages Deserve to Be Reconnected
Treat every candidate as an editorial decision, not an automatic linking task. The key question is whether this URL should serve visitors as a distinct, current destination. Search traffic and backlinks can help prioritize review, but a page with no recorded traffic may still fill an important information gap.
Reconnect: the page is useful, accurate, distinct from other pages, and appropriate for public discovery.
Update, then reconnect: the topic is valuable, but the content contains outdated instructions, broken references, or incomplete answers.
Consolidate: another page serves substantially the same need. Combine useful material and, where appropriate, redirect the retired URL to a close replacement.
Keep intentionally excluded: the page supports a specific workflow but should not appear in ordinary browsing or search results. Document the reason and review its technical controls.
Retire: the content has no continuing purpose and no suitable replacement. Remove it deliberately and return an appropriate not-found or gone response rather than redirecting unrelated content to the homepage.
Check technical eligibility before adding links for SEO. A page blocked from crawling, marked noindex, or canonicalized to another URL needs a separate decision. If it should be a searchable destination, resolve conflicting signals first. If those controls are intentional, do not remove them simply because an orphan report flagged the page.
For a hypothetical example, consider an appliance retailer with a disconnected filter-replacement guide and an expired promotion page. The guide still answers a common maintenance question, so it may deserve updated instructions and links from compatible product pages. The promotion may instead need retirement or a redirect to a genuinely equivalent continuing offer. The same orphan status leads to different actions because the pages serve different purposes.
An unlinked page is not private. If a URL contains sensitive information, use authentication and appropriate access controls. Neither keeping it out of navigation nor adding a noindex directive is a substitute for restricting access.
Choose the Right Internal Links and Placement
Choose source pages by reader need and topical relationship, not just by their traffic or perceived authority. Ask where someone would reasonably need the orphan page next. A troubleshooting article belongs near the problem it solves; a buying guide belongs in the relevant category or comparison journey. There is no universal number of internal links that makes a page adequately connected.
Match the placement to the page's role
Contextual body link: use when the destination expands on a specific question, step, or term in an existing article.
Category or topic hub: use when the page is a durable resource that readers should find while browsing a subject.
Product or service page: use when the destination supports selection, setup, maintenance, or another relevant task.
Related-content module: use when recommendations are genuinely related and the module outputs crawlable links.
Primary navigation: reserve for destinations important enough to justify persistent exposure across the site.
Write anchor text that describes the destination in the source sentence. For the hypothetical maintenance guide, an anchor such as filter replacement instructions communicates more than click here. Do not force the same keyword phrase into every link or add a paragraph solely to carry an anchor. The surrounding explanation should make the recommendation useful.
Link directly to the preferred, working URL rather than through an avoidable redirect. Use ordinary HTML anchors with href attributes that crawlers can follow. A button that only triggers a script or a search form that can reveal a page is not a reliable substitute for a navigable link. Check the rendered output rather than assuming the CMS editor produces the intended markup.
Make sure the source page is itself reachable. Adding a link from one orphan to another can leave both isolated. For a disconnected content cluster, reconnect an appropriate hub or entry page to the established site structure, then review links within the cluster. Breadcrumbs can help express hierarchy, but breadcrumbs on the orphan page only provide outgoing links; they do not create an incoming path to it.
If many pages became orphaned at once, inspect the shared cause. A removed category, broken pagination, changed recommendation module, or migration may have cut off an entire section. Restoring a sensible template-level path is often more maintainable than editing dozens of unrelated articles. Avoid replacing the problem with a sitewide list of every URL.
Verify Discovery, Indexing, and Organic Performance
Verification has three separate stages: confirming the internal path, checking search-engine access and indexing signals, and observing performance. Complete them in that order. A rise in impressions cannot prove that your link implementation is sound, and a successful crawl does not prove that a search engine has indexed the destination.
Recrawl from the normal site entry points without relying on the candidate URL list. Confirm that the destination is now discovered through internal links.
Inspect the incoming links. Verify the source URLs, anchor text, placement, and destination response, and ensure the route does not depend on a disconnected source page.
Check the destination's canonical, robots directives, and content rendering. Ensure your intended searchable page is not sending conflicting signals.
Use Google Search Console URL Inspection to review available indexing information and, when useful, test live access. A live test does not establish that the URL is indexed.
Review subsequent search impressions, clicks, relevant queries, and useful on-page actions. Annotate the change date and any simultaneous content or technical updates.
Requesting indexing can be appropriate for an important updated URL, but it does not replace durable internal links or guarantee inclusion. Keep suitable canonical, indexable URLs in your XML sitemap as a complementary discovery mechanism. Do not use sitemap inclusion as the sole measure of a successful repair.
Allow time for recrawling and reassessment; there is no fixed waiting period that applies to every site. Compare performance over periods appropriate to your traffic volume and seasonality. If a page gains visibility after both a content rewrite and new internal links, report the combined change rather than attributing the entire result to linking.
If the page remains undiscovered in your own recrawl, return to implementation: check whether the source is reachable, the link is rendered, and crawl restrictions are interfering. If it is discovered but not indexed, investigate duplication, canonical selection, access issues, and the page's distinct usefulness. If it is indexed but receives little relevant traffic, revisit search intent and content quality rather than adding more links indiscriminately.
Start with a manageable batch of high-value candidates. Assign each one a decision, a relevant source page, an owner, and a verification status. Once those repairs are confirmed, make incoming-link checks part of publishing and migration reviews so useful pages do not depend on someone remembering their URLs.