SEONovember 13, 2026
SEO for JavaScript Rendering: Diagnose Pages That Search Engines See Differently
Learn how to spot gaps between a page’s initial HTML and its rendered version, then identify whether they affect indexing or rankings. Use a practical diagnostic workflow to prioritize fixes for client-side content and links.
A page that looks complete in your browser can still deliver little useful content in its initial HTML, lose internal links during rendering, or send indexing signals that contradict what you see. Diagnose those differences before changing frameworks or rebuilding templates. The practical approach is to compare three layers: the server response, the rendered page, and the evidence available from search engine indexing tools.
Start with one affected URL and one healthy URL from the same template. Choose pages that should be publicly accessible and indexable. Working through a matched pair makes it easier to distinguish a sitewide rendering problem from missing data, an unusual page state, or a URL-specific indexing issue.
How JavaScript Changes What a Page Delivers
A browser first receives an HTTP response, usually containing HTML. It then parses that document, requests resources, executes JavaScript, and builds the document object model, or DOM. JavaScript can add the main article, fetch product information, replace headings, change metadata, and create navigation links. The rendered DOM can therefore differ substantially from the HTML the server originally returned.
Search engines do not all process JavaScript in the same way. Google can render JavaScript, but successful rendering still depends on accessible resources, supported behavior, and a page that can finish its essential work without user interaction. Other crawlers may execute little or no JavaScript. Rendering capability is not a guarantee that every fetched page will be rendered, indexed, or selected for search results.
- Client-side rendering often delivers a small HTML shell and relies on JavaScript to populate the page. This makes scripts and data requests dependencies for content discovery.
- Server-side rendering delivers page content in the HTML response. JavaScript may then hydrate that markup to make it interactive.
- Static generation produces HTML ahead of a request. It can reduce runtime dependencies, but freshness depends on how pages are rebuilt or updated.
- Hybrid implementations use different approaches by route or component. A server-rendered heading does not prove that descriptions, related links, or metadata are also server-rendered.
The diagnostic question is not simply whether the site uses JavaScript. It is whether the information needed to understand, discover, and index each URL is consistently available to crawlers. A page can be fully client-rendered and accessible, or server-rendered and still broken by incorrect status codes, directives, or hydration behavior.
Compare Initial HTML With Rendered Output
Use the same exact URL throughout the comparison, including any trailing slash or query string. Record the test time, final destination after redirects, HTTP status, browser state, and page template. Otherwise, you may accidentally compare different URL variants or different versions of the page.
Step 1: Capture the server response
Open the browser's developer tools, select the Network panel, and reload the page. Inspect the main document request, including its response body and headers. This shows what arrived for that request before JavaScript modified the document. View Source is also useful for inspecting HTML, but the Network response is easier to associate with a specific load. Do not use the Elements panel as a substitute for source HTML; it shows the current DOM.
Search the response for a distinctive sentence from the main content, an important internal link, the title element, the canonical link, and robots directives. Note whether content exists as visible HTML or only inside a script containing serialized data. A product description stored in a data object is not equivalent to that description appearing as readable page content.
Step 2: Inspect the rendered page in a clean session
Load the URL directly in a private or otherwise clean browser session without logging in. Let the page initialize without clicking, typing, or scrolling, then inspect the DOM in the Elements panel. Check for the same content, links, and metadata you searched for in the response. Record anything that appears only after an interaction.
Test both a direct load and navigation to the URL from elsewhere within the site. A client-side router may display a page correctly after an internal click even though requesting that URL directly returns an error or an incomplete shell. Also watch for the reverse problem: valid server-rendered content that disappears when hydration runs.
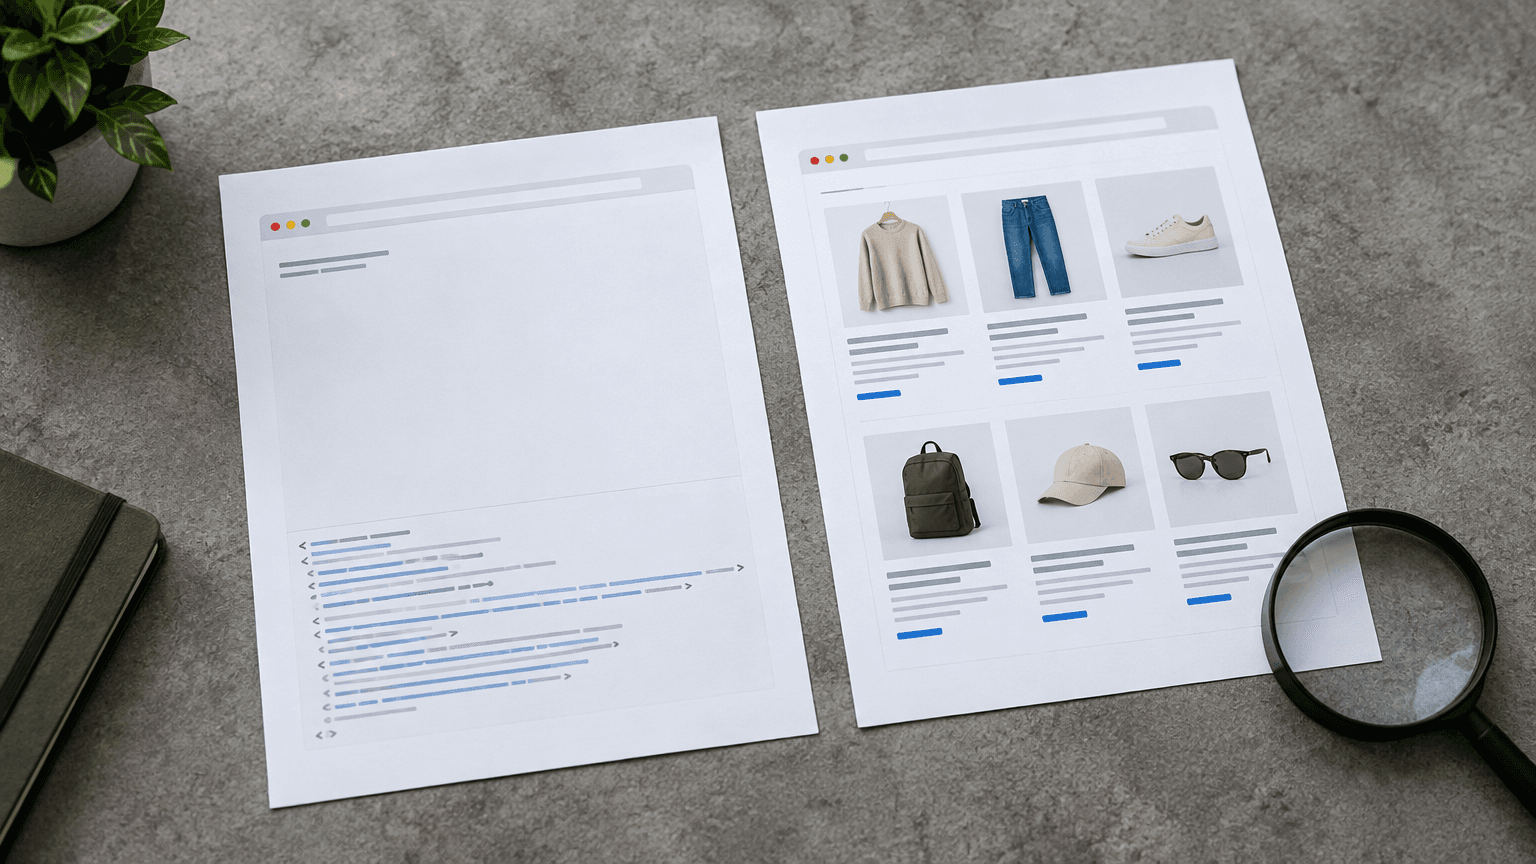
Step 3: Compare with a search engine rendering test
For Google, use Search Console's URL Inspection tool and run a live test where available. Inspect the rendered HTML, screenshot, and reported resource or JavaScript issues. Search the rendered HTML for your selected sentence and links rather than relying only on the screenshot. A screenshot can reveal an error screen or loading state, but it cannot establish that canonical tags or link destinations are correct.
A successful live test is not proof of indexing. It describes a current test fetch and rendering attempt. The indexed report may reflect an earlier crawl, and indexing still depends on factors beyond whether JavaScript executed.
Keep a small comparison record with one row per important element and columns for initial HTML, browser DOM, search engine rendered HTML, and available indexed evidence. Use specific observations such as description absent or canonical changed to category URL, rather than a single pass/fail label for the whole page.
Test Content, Links, and Metadata
Once you have the three views, check elements in order of their role. Main content tells a search engine what the page offers. Links make other URLs discoverable. Metadata and directives help describe the page and communicate indexing preferences. Each can fail independently.
Check meaningful content, not just a populated screen
- Confirm that the primary heading and substantive text are present, not just navigation, loading placeholders, or a generic application message.
- Inspect data requests that supply essential content. Look for failed responses, authentication requirements, cross-origin errors, and request chains that never complete.
- Identify dependencies on cookies, local storage, location permission, or consent choices. A returning visitor's saved state can hide a failure that affects a fresh session.
- Test important content revealed by tabs, accordions, scrolling, or load-more controls. Distinguish content already present in the DOM from content fetched only after interaction.
- For long lists, check whether virtualization removes most items from the DOM. If individual items need discovery, provide accessible linked pages rather than relying only on scrolling.
Hypothetical example: a category page initially contains a heading and spinner. Products appear in your browser because a saved location selects an inventory endpoint. A clean session receives no location and stays empty. The underlying issue is a state-dependent content request, not evidence that the search engine cannot process the site's framework.
Check that navigation exposes real URLs
Important navigation should use anchor elements with usable href values. A button or clickable container that changes routes through an event handler is not an equivalent discovery mechanism. Inspect the actual markup, resolve relative destinations, and open representative links directly. Confirm that they lead to the intended pages rather than fragments, temporary routes, or errors.
For pagination and infinite scrolling, provide crawlable paths to deeper content. Do not assume a crawler will repeatedly scroll or activate a load-more button. Each important destination should also work as a direct request; exposing a link does not fix a destination that the server cannot serve.
Check metadata across loads and route changes
Compare the title, meta description, canonical link, robots meta tags, and any relevant hreflang or structured data between the response and rendered DOM. Look for duplicates, generic defaults, and values left over from the previous route. Navigate between two different page types and then reload each directly to expose stale head-management state.
Prefer consistent, correct signals in the initial HTML when your architecture allows it. In particular, do not deliver an initial noindex directive and rely on JavaScript to remove it: Google may skip rendering after encountering noindex. Likewise, avoid sending one canonical URL from the server and replacing it with another in the browser. Structured data should describe the content actually available on the page, not content that failed to load.
Check Indexing Signals Before Changing Code
A rendering difference is worth investigating, but it is not automatically the reason a URL is absent from search. Before commissioning a rendering change, verify that crawling and indexing are permitted and that the search engine is evaluating the URL you intend.
- Check the document's HTTP response and redirect chain. An error page displayed with a successful status can be treated as a soft 404; a browser-friendly screen does not correct an unsuitable status.
- Review robots.txt access for the page and resources required to render it. A blocked script or content endpoint can matter even when the document itself is allowed.
- Inspect both robots meta tags and X-Robots-Tag response headers. JavaScript changes to the DOM do not remove a restrictive HTTP header.
- Compare the declared canonical with Google's selected canonical where Search Console provides it. Investigate duplicate URL variants and conflicting internal links or sitemap entries.
- Confirm that the URL is discoverable through relevant internal links. A sitemap can help discovery, but it does not guarantee indexing or replace useful site navigation.
- Check for login walls, access challenges, rate limits, and server failures. Use logs when available to investigate actual requests rather than assuming a browser test represents crawler access.
Use Search Console's indexed information to establish timing and context: the reported crawl date, indexing status, fetch details, and canonical information where available. If the last crawl predates a fix, the indexed evidence cannot yet validate that fix. If the rendered content is complete but the URL is not indexed, investigate duplication, limited unique value, discovery, and other indexing factors rather than repeatedly changing rendering code.
Search result snippets and site: searches are secondary clues, not complete indexing audits. Snippets can vary by query and may not reproduce the page's meta description. Use inspection evidence and crawl timing to interpret apparent mismatches.
Prioritize Fixes and Verify the Results
Prioritize by the importance of the affected information, the number of URLs sharing the defect, and the strength of your evidence. Missing primary content across a major template deserves attention before a minor description mismatch. A confirmed access block usually needs resolution before you can judge rendering reliably.
- Restore access and correct signals first: fix unintended noindex directives, blocked essential resources, incorrect redirects, unsuitable status codes, and canonical errors.
- Repair content delivery next: resolve failed data requests, remove unnecessary session dependencies, and prevent hydration from deleting valid markup.
- Restore discovery paths: replace navigation-only event handlers with usable links and provide linked routes to content hidden behind interaction.
- Consider server-side rendering or static generation for essential content when client-side dependencies remain unreliable. Select the approach by template and freshness needs, not by framework reputation.
- Improve metadata consistency and add regression checks once the core content and discovery paths work.
Moving content into server-delivered HTML can reduce dependence on rendering, but it introduces its own operational work. Server rendering can increase backend workload and complicate caching; static generation needs a reliable update strategy. Neither approach automatically fixes poor navigation, duplicate pages, or incorrect directives. Serve equivalent essential content to users and crawlers rather than building a separate, potentially divergent crawler-only page.
Verify delivery first, then wait for indexing evidence
After deployment, repeat the original comparison on the same URLs. Confirm the initial response, clean-session DOM, direct-route behavior, and search engine live rendering. Check that the deployed HTML references available script assets and that caches are not serving incompatible versions. Test a small set of sibling URLs to make sure a template fix works beyond the original example.
Define acceptance criteria before calling the issue resolved. For example: the primary description appears without interaction, related links contain valid destinations, the canonical remains consistent, and no unintended indexing restriction appears in the response or rendered output. These are verifiable delivery outcomes; improved rankings are not a suitable technical acceptance test.
For important corrected URLs, request indexing through Search Console where appropriate, then monitor for a subsequent crawl and updated indexing information. There is no guaranteed recrawl or indexing deadline. Track search visibility separately over time, accounting for other site changes, rather than attributing every movement to the rendering fix.
Your next step is to select one suspect URL and capture its initial HTML, clean-session rendered DOM, and Search Console evidence. Mark the first meaningful divergence, confirm whether it affects other pages on the same template, and turn that finding into a specific fix with a repeatable verification test.